ML: Classifier

# Setup - Run only once per Kernel App
%conda install https://anaconda.org/conda-forge/openjdk/11.0.1/download/linux-64/openjdk-11.0.1-hacce0ff_1021.tar.bz2

# install PySpark
!pip install sagemaker_pyspark

# restart kernel
from IPython.core.display import HTML
HTML("<script>Jupyter.notebook.kernel.restart()</script>")

Downloading and Extracting Packages:
                                                                                

Downloading and Extracting Packages:

Preparing transaction: done
Verifying transaction: done
Executing transaction: done

Note: you may need to restart the kernel to use updated packages.
Collecting sagemaker_pyspark
  Using cached sagemaker_pyspark-1.4.5-py3-none-any.whl
Collecting pyspark==3.3.0 (from sagemaker_pyspark)
  Using cached pyspark-3.3.0-py2.py3-none-any.whl
Requirement already satisfied: numpy in /opt/conda/lib/python3.10/site-packages (from sagemaker_pyspark) (1.26.4)
Collecting py4j==0.10.9.5 (from pyspark==3.3.0->sagemaker_pyspark)
  Using cached py4j-0.10.9.5-py2.py3-none-any.whl.metadata (1.5 kB)
Using cached py4j-0.10.9.5-py2.py3-none-any.whl (199 kB)
Installing collected packages: py4j, pyspark, sagemaker_pyspark
Successfully installed py4j-0.10.9.5 pyspark-3.3.0 sagemaker_pyspark-1.4.5
WARNING: Running pip as the 'root' user can result in broken permissions and conflicting behaviour with the system package manager. It is recommended to use a virtual environment instead: https://pip.pypa.io/warnings/venv
import sagemaker
sess = sagemaker.Session()
bucket = sess.default_bucket() 
print(f"the default SageMaker region specific bucket for this account is {bucket}")
sagemaker.config INFO - Not applying SDK defaults from location: /etc/xdg/sagemaker/config.yaml
sagemaker.config INFO - Not applying SDK defaults from location: /root/.config/sagemaker/config.yaml
the default SageMaker region specific bucket for this account is sagemaker-us-east-1-658225707433
from pyspark.sql import SparkSession

spark = (
    SparkSession.builder.appName("PySparkApp-Preds")
    .config("spark.jars.packages", "org.apache.hadoop:hadoop-aws:3.2.2")
    .config(
        "fs.s3a.aws.credentials.provider",
        "com.amazonaws.auth.ContainerCredentialsProvider",
    )
    .getOrCreate()
)

print(spark.version)
Warning: Ignoring non-Spark config property: fs.s3a.aws.credentials.provider
Ivy Default Cache set to: /root/.ivy2/cache
The jars for the packages stored in: /root/.ivy2/jars
org.apache.hadoop#hadoop-aws added as a dependency
:: resolving dependencies :: org.apache.spark#spark-submit-parent-21bbc87a-14f4-41c6-ad60-cbc2d81d4376;1.0
    confs: [default]
    found org.apache.hadoop#hadoop-aws;3.2.2 in central
    found com.amazonaws#aws-java-sdk-bundle;1.11.563 in central
:: resolution report :: resolve 612ms :: artifacts dl 34ms
    :: modules in use:
    com.amazonaws#aws-java-sdk-bundle;1.11.563 from central in [default]
    org.apache.hadoop#hadoop-aws;3.2.2 from central in [default]
    ---------------------------------------------------------------------
    |                  |            modules            ||   artifacts   |
    |       conf       | number| search|dwnlded|evicted|| number|dwnlded|
    ---------------------------------------------------------------------
    |      default     |   2   |   0   |   0   |   0   ||   2   |   0   |
    ---------------------------------------------------------------------
:: retrieving :: org.apache.spark#spark-submit-parent-21bbc87a-14f4-41c6-ad60-cbc2d81d4376
    confs: [default]
    0 artifacts copied, 2 already retrieved (0kB/27ms)
Setting default log level to "WARN".
To adjust logging level use sc.setLogLevel(newLevel). For SparkR, use setLogLevel(newLevel).
:: loading settings :: url = jar:file:/opt/conda/lib/python3.10/site-packages/pyspark/jars/ivy-2.5.0.jar!/org/apache/ivy/core/settings/ivysettings.xml
24/05/03 17:08:47 WARN NativeCodeLoader: Unable to load native-hadoop library for your platform... using builtin-java classes where applicable
3.3.0
sc = spark.sparkContext
sc._jsc.hadoopConfiguration().set("mapred.output.committer.class", "org.apache.hadoop.mapred.FileOutputCommitter")
from pyspark.sql.types import *
from pyspark.sql.functions import length, when, udf, col
from pyspark.ml import Pipeline

from pyspark.ml.feature import VectorAssembler, StringIndexer, OneHotEncoder, StandardScaler
from pyspark.ml.classification import LogisticRegression

from pyspark.ml.evaluation import BinaryClassificationEvaluator, MulticlassClassificationEvaluator
from sklearn.metrics import confusion_matrix
from pyspark.ml.tuning import CrossValidator, ParamGridBuilder

Starting good stuff:

PRocessing data:

# ### original data: 

# original_df = spark.read.parquet("s3a://sagemaker-us-east-1-658225707433/project/roberta_tagged/", header=True)
# original_df = original_df.select("body", "author", "gilded", "score", "edited", "month", "year")
# original_df = original_df.withColumnRenamed('body', 'og_body')
# original_df = original_df.withColumnRenamed('author', 'og_author')
# original_df = original_df.withColumnRenamed('month', 'og_month')
# original_df = original_df.withColumnRenamed('year', 'og_year')


# original_df.printSchema()
# # original_df.show()
s3_file_path =  f"s3a://sagemaker-us-east-1-658225707433/project/roberta_sentiment_tagged/"
deduplicated_df = spark.read.parquet(s3_file_path, header=True)
deduplicated_df.printSchema()
root
 |-- month: integer (nullable = true)
 |-- year: integer (nullable = true)
 |-- author: string (nullable = true)
 |-- body: string (nullable = true)
 |-- controversiality: long (nullable = true)
 |-- subreddit: string (nullable = true)
 |-- env: boolean (nullable = true)
 |-- labels: string (nullable = true)
 |-- cleaned_body: string (nullable = true)
 |-- sentiment: array (nullable = true)
 |    |-- element: struct (containsNull = true)
 |    |    |-- annotatorType: string (nullable = true)
 |    |    |-- begin: integer (nullable = true)
 |    |    |-- end: integer (nullable = true)
 |    |    |-- result: string (nullable = true)
 |    |    |-- metadata: map (nullable = true)
 |    |    |    |-- key: string
 |    |    |    |-- value: string (valueContainsNull = true)
 |    |    |-- embeddings: array (nullable = true)
 |    |    |    |-- element: float (containsNull = true)
 |-- gilded: long (nullable = true)
 |-- edited: string (nullable = true)
 |-- env_terms: array (nullable = true)
 |    |-- element: string (containsNull = true)
 |-- score: long (nullable = true)
 |-- sentiment_exploded: struct (nullable = true)
 |    |-- annotatorType: string (nullable = true)
 |    |-- begin: integer (nullable = true)
 |    |-- end: integer (nullable = true)
 |    |-- result: string (nullable = true)
 |    |-- metadata: map (nullable = true)
 |    |    |-- key: string
 |    |    |-- value: string (valueContainsNull = true)
 |    |-- embeddings: array (nullable = true)
 |    |    |-- element: float (containsNull = true)
 |-- sentiment_result: string (nullable = true)
print(deduplicated_df.count())
[Stage 3146:=====================================>                  (2 + 1) / 3]                                                                                
19532
deduplicated_df.select("env").distinct().show()
[Stage 3172:=====================================>                  (2 + 1) / 3]                                                                                
+-----+
|  env|
+-----+
| true|
|false|
+-----+

df_1 = deduplicated_df.withColumn("body_length", length(deduplicated_df["body"]))
df_1 = df_1.withColumn("env_bool", when(df_1["env"] == "true", 1).otherwise(0))
# df_1 = df_1.withColumn("edited_bool", when(df_1["edited"] == "true", 1).otherwise(0))

# Is it a claim or not?
df_1 = df_1.withColumn("claim_bool", when(df_1["labels"] == "LABEL_0", 0).otherwise(1))
df_1.select("gilded").distinct().show()
[Stage 3181:==================>                                     (1 + 2) / 3]                                                                                
+------+
|gilded|
+------+
|     0|
|     1|
+------+

Skeptic sites:

def contains_any(string, arr):
    if string is None:
        return False
    return any(x in string.lower() for x in arr)
contains_any_udf = udf(lambda x: contains_any(x, skeptic_sites), BooleanType())

skeptic_sites_csv_path = f"s3a://{bucket}/project/blogs_and_CTTs.csv"
skeptic_sites = [x["website"] 
                 for x in spark.read.csv(skeptic_sites_csv_path, header=True)\
                 .select("website").collect()
                ]
df_1 = df_1.withColumn("skeptic_site", contains_any_udf(col("body")))   
df_1 = df_1.select("body_length", "subreddit", "controversiality", "env_bool", "claim_bool", 
                   "sentiment_result", "skeptic_site",  "gilded", "score")
df_1.select("subreddit").distinct().show()
[Stage 3192:=====================================>                  (2 + 1) / 3]                                                                                
+---------------+
|      subreddit|
+---------------+
|     conspiracy|
|climateskeptics|
|  climatechange|
+---------------+

Creating pipeline:

indexer_subreddit = StringIndexer(inputCol="subreddit", outputCol="subreddit_indexed")
encoder_subreddit = OneHotEncoder(inputCol="subreddit_indexed", outputCol="subreddit_encoded")

indexer_sentiment = StringIndexer(inputCol="sentiment_result", outputCol="sentiment_result_indexed")
encoder_sentiment = OneHotEncoder(inputCol="sentiment_result_indexed", outputCol="sentiment_result_encoded")
# deduplicated_df = deduplicated_df.select("body_length", "subreddit", "controversiality_bool", "controversiality", "env", "claim_bool", "sentiment_result")


assembler = VectorAssembler(inputCols=["body_length", 
                                       "controversiality",  
                                       "subreddit_encoded",
                                       "sentiment_result_encoded",
                                       "skeptic_site",
                                      "env_bool", 
                                       "gilded", 
                                       "score"], outputCol="features")


standardscaler=StandardScaler().setInputCol("features").setOutputCol("Scaled_features")
# raw_data=assembler.transform(deduplicated_df)
# raw_data.select("features").show(truncate=False)
# raw_data=standardscaler.fit(raw_data).transform(raw_data)
# raw_data.select("features","Scaled_features").show(5)
pipeline = Pipeline(stages=[indexer_subreddit, encoder_subreddit, 
                            indexer_sentiment, encoder_sentiment, 
                            assembler, 
                            standardscaler])

prepared_data = pipeline.fit(df_1).transform(df_1)
prepared_data.show(5)
[Stage 3204:>                                                       (0 + 1) / 1]                                                                                
+-----------+---------------+----------------+--------+----------+----------------+------------+------+-----+-----------------+-----------------+------------------------+------------------------+--------------------+--------------------+
|body_length|      subreddit|controversiality|env_bool|claim_bool|sentiment_result|skeptic_site|gilded|score|subreddit_indexed|subreddit_encoded|sentiment_result_indexed|sentiment_result_encoded|            features|     Scaled_features|
+-----------+---------------+----------------+--------+----------+----------------+------------+------+-----+-----------------+-----------------+------------------------+------------------------+--------------------+--------------------+
|        186|  climatechange|               0|       0|         0|        positive|       false|     0|    1|              0.0|    (2,[0],[1.0])|                     0.0|           (2,[0],[1.0])|(10,[0,2,4,9],[18...|(10,[0,2,4,9],[0....|
|        412|  climatechange|               0|       0|         0|        positive|       false|     0|    1|              0.0|    (2,[0],[1.0])|                     0.0|           (2,[0],[1.0])|(10,[0,2,4,9],[41...|(10,[0,2,4,9],[0....|
|        203|     conspiracy|               0|       0|         0|        negative|       false|     0|  -40|              1.0|    (2,[1],[1.0])|                     1.0|           (2,[1],[1.0])|(10,[0,3,5,9],[20...|(10,[0,3,5,9],[0....|
|         67|     conspiracy|               0|       0|         0|        positive|       false|     0|   -1|              1.0|    (2,[1],[1.0])|                     0.0|           (2,[0],[1.0])|(10,[0,3,4,9],[67...|(10,[0,3,4,9],[0....|
|         83|climateskeptics|               0|       0|         0|        positive|       false|     0|   53|              2.0|        (2,[],[])|                     0.0|           (2,[0],[1.0])|(10,[0,4,9],[83.0...|(10,[0,4,9],[0.15...|
+-----------+---------------+----------------+--------+----------+----------------+------------+------+-----+-----------------+-----------------+------------------------+------------------------+--------------------+--------------------+
only showing top 5 rows
Splitting data:

(train, test) = prepared_data.randomSplit([0.7, 0.3], seed=42)
print(train.count())
print(test.count())
                                                                                [Stage 3208:=====================================>                  (2 + 1) / 3]                                                                                
13785
5747

Logistic Regression:

# lrModel = LogisticRegression(labelCol= 'claim_bool', 
#                              featuresCol='Scaled_features',
#                              maxIter= 10).fit(train)

# lr_predictions = lrModel.transform(test)
# # Evaluate model
# lr_predictions = lr_predictions.withColumnRenamed('claim_bool', 'label')
# evaluator = BinaryClassificationEvaluator()
# evaluator.evaluate(lr_predictions)
# lr_predictions = lr_predictions.select("label", "prediction", "probability")

XGBoost:

# from pyspark.ml.classification import GBTClassifier

# spark_reg_estimator = GBTClassifier(labelCol= 'claim_bool', 
#                              featuresCol='Scaled_features',
#                              maxIter= 10).fit(train)

# xgb_predictions = spark_reg_estimator.transform(test)

# # Evaluate model
# xg_predictions = xgb_predictions.withColumnRenamed('claim_bool', 'label')
# evaluator = BinaryClassificationEvaluator()
# evaluator.evaluate(xg_predictions)
# xg_predictions = xg_predictions.select("label", "prediction", "probability")
Evaluation metrics from lab:

# lr_y_pred=lr_predictions.select("prediction").collect()
# lr_y_orig=lr_predictions.select("label").collect()
# lr_cm = confusion_matrix(lr_y_orig, lr_y_pred)
# print("Confusion Matrix for Linear Regression:")
# print(lr_cm)
# lr_evaluator = MulticlassClassificationEvaluator(labelCol="label", predictionCol="prediction", metricName="accuracy")
# lr_accuracy = lr_evaluator.evaluate(lr_predictions)
# print(f"LR Model accuracy: {lr_accuracy}")
# gb_y_pred=xg_predictions.select("prediction").collect()
# gb_y_orig=xg_predictions.select("label").collect()
# xg_cm = confusion_matrix(gb_y_orig, gb_y_pred)
# print("Confusion Matrix for GBTClassifier:")
# print(xg_cm)
# xg_evaluator = MulticlassClassificationEvaluator(labelCol="label", predictionCol="prediction", metricName="accuracy")
# xg_accuracy = xg_evaluator.evaluate(xg_predictions)
# print(f"XG Model accuracy: {xg_accuracy}")

Oversampling minority:


import numpy as np
import pandas as pd
import matplotlib.pyplot as plt

from pyspark.sql import SparkSession
from pyspark.sql import functions as F
from pyspark.sql.types import StructType, StructField, DoubleType, StringType, IntegerType
from pyspark.ml.feature import VectorAssembler, StringIndexer
from pyspark.ml.classification import RandomForestClassifier, RandomForestClassificationModel
from pyspark.ml.evaluation import BinaryClassificationEvaluator, MulticlassClassificationEvaluator
from pyspark.mllib.evaluation import MulticlassMetrics

from sklearn.metrics import confusion_matrix
# Create undersampling function
# https://medium.com/data-and-beyond/exploring-pyspark-ml-for-machine-learning-handling-class-imbalances-part-2-2-f9113f6b40ba

def oversample_minority(df, ratio=1):
    '''
    ratio is the ratio of majority to minority
    Eg. ratio 1 is equivalent to majority:minority = 1:1
    ratio 5 is equivalent to majority:minority = 5:1
    '''
    minority_count = df.filter(F.col('claim_bool')==1).count()
    majority_count = df.filter(F.col('claim_bool')==0).count()
    
    balance_ratio = majority_count / minority_count
    
    print(f"Initial Majority:Minority ratio is {balance_ratio:.2f}:1")
    if ratio >= balance_ratio:
        print("No oversampling of minority was done as the input ratio was more than or equal to the initial ratio.")
    else:
        print(f"Oversampling of minority done such that Majority:Minority ratio is {ratio}:1")
    
    oversampled_minority = df.filter(F.col('claim_bool')==1)\
                                .sample(withReplacement=True, fraction=(balance_ratio/ratio),seed=88)
    oversampled_df = df.filter(F.col('claim_bool')==0).union(oversampled_minority)
    
    return oversampled_df
oversampled_train_df = oversample_minority(train,1)
[Stage 3214:=====================================>                  (2 + 1) / 3]                                                                                
Initial Majority:Minority ratio is 9.66:1
Oversampling of minority done such that Majority:Minority ratio is 1:1
lrModel_oversampled = LogisticRegression(labelCol= 'claim_bool', 
                             featuresCol='Scaled_features',
                             maxIter= 10).fit(oversampled_train_df)
                                                                                
lr_predictions_oversampled = lrModel_oversampled.transform(test)
# Evaluate model
lr_predictions_oversampled = lr_predictions_oversampled.withColumnRenamed('claim_bool', 'label')
evaluator = BinaryClassificationEvaluator()
evaluator.evaluate(lr_predictions_oversampled)
lr_predictions_oversampled = lr_predictions_oversampled.select("label", "prediction", "probability")


lr_y_pred_oversampled=lr_predictions_oversampled.select("prediction").collect()
lr_y_orig_oversampled=lr_predictions_oversampled.select("label").collect()
lr_cm_oversampled = confusion_matrix(lr_y_orig_oversampled, lr_y_pred_oversampled)
print("Confusion Matrix for Linear Regression:")
print(lr_cm_oversampled)

lr_evaluator_oversampled = MulticlassClassificationEvaluator(labelCol="label", predictionCol="prediction", metricName="accuracy")
lr_accuracy_oversampled = lr_evaluator_oversampled.evaluate(lr_predictions_oversampled)
print(f"LR Model accuracy: {lr_accuracy_oversampled}")
                                                                                [Stage 3254:=====================================>                  (2 + 1) / 3]                                                                                
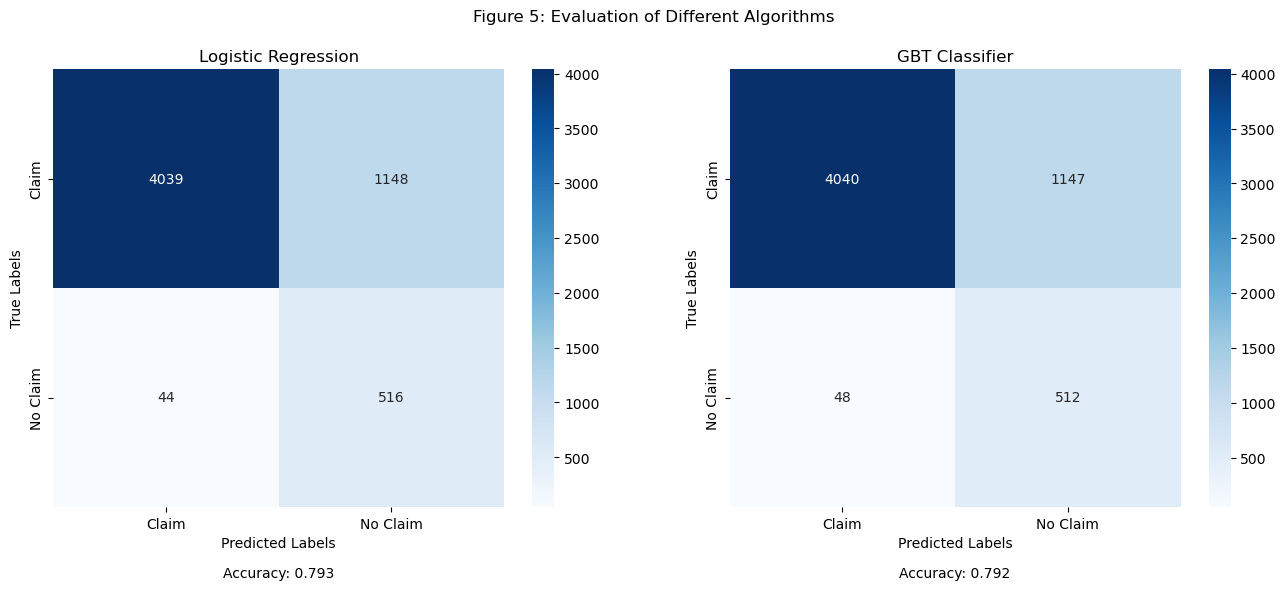
Confusion Matrix for Linear Regression:
[[4039 1148]
 [  44  516]]
LR Model accuracy: 0.7925874369236123
from pyspark.ml.classification import GBTClassifier

spark_reg_estimator_oversampled = GBTClassifier(labelCol= 'claim_bool', 
                             featuresCol='Scaled_features',
                             maxIter= 10).fit(oversampled_train_df)

xgb_predictions_oversampled = spark_reg_estimator_oversampled.transform(test)


# Evaluate model
xg_predictions_oversampled = xgb_predictions_oversampled.withColumnRenamed('claim_bool', 'label')
evaluator = BinaryClassificationEvaluator()
evaluator.evaluate(xg_predictions_oversampled)
xg_predictions_oversampled = xg_predictions_oversampled.select("label", "prediction", "probability")

gb_y_pred_oversampled=xg_predictions_oversampled.select("prediction").collect()
gb_y_orig_oversampled=xg_predictions_oversampled.select("label").collect()
xg_cm_oversampled = confusion_matrix(gb_y_orig_oversampled, gb_y_pred_oversampled)
print("Confusion Matrix for GBTClassifier:")
print(xg_cm_oversampled)
                                                                                
Confusion Matrix for GBTClassifier:
[[4040 1147]
 [  48  512]]
xg_evaluator_oversampled = MulticlassClassificationEvaluator(labelCol="label", predictionCol="prediction", metricName="accuracy")
xg_accuracy_oversampled = xg_evaluator_oversampled.evaluate(xg_predictions_oversampled)
print(f"XG Model accuracy: {xg_accuracy_oversampled}")
[Stage 3373:=====================================>                  (2 + 1) / 3]                                                                                
XG Model accuracy: 0.7920654254393596

Exporting things for ML analysis:

import json
json.dump({'lr_cm_oversampled' : lr_cm_oversampled.tolist(),
           'lr_acc_oversampled_oversampled' : lr_accuracy_oversampled,
           'xg_cm_oversampled' : xg_cm_oversampled.tolist(),
           'xg_acc_oversampled' : xg_accuracy_oversampled,
           
          },
          fp = open('ml_metrics_comparison_oversampled.json','w'))

Hyperparameter Tuning:

# Block for Hyperparameter tuning


evaluator_lr =  MulticlassClassificationEvaluator(labelCol="claim_bool", predictionCol="prediction", metricName="accuracy")

lrModel_oversampled = LogisticRegression(labelCol= 'claim_bool', 
                             featuresCol='Scaled_features',
                             maxIter= 10)

paramGrid = ParamGridBuilder().addGrid(lrModel_oversampled.regParam,[0.02, 0.04, 0.06, 0.08, 0.1, 0.12])\
            .addGrid(lrModel_oversampled.elasticNetParam,[0, 0.2, 0.4, 0.6, 0.8, 1]).build()


crossval = CrossValidator(estimator = lrModel_oversampled,
                          estimatorParamMaps = paramGrid,
                          evaluator = evaluator_lr,
                          numFolds = 3)


cvModel = crossval.fit(oversampled_train_df)

# Get the best model from CrossValidator
best_model = cvModel.bestModel

# Extract best model's hyperparameters
best_reg_param = best_model.getOrDefault('regParam')
best_elastic_net_param = best_model.getOrDefault('elasticNetParam')

print("Best model hyperparameters:")
print("Regularization Parameter (regParam):", best_reg_param)
print("Elastic Net Parameter (elasticNetParam):", best_elastic_net_param)
                                                                                
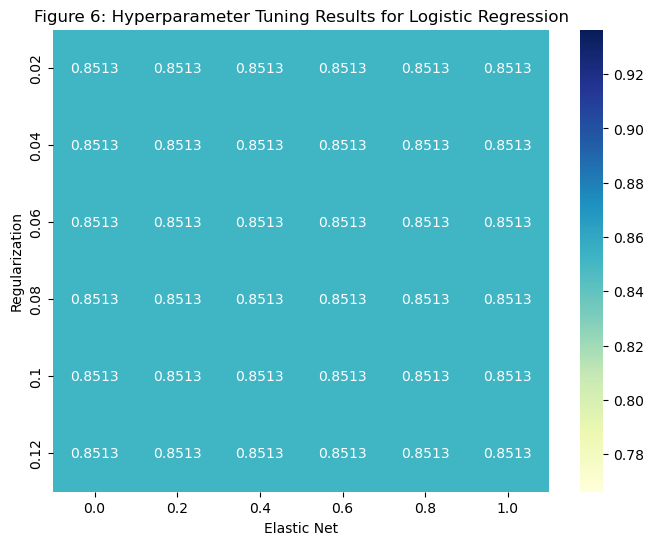
Best model hyperparameters:
Regularization Parameter (regParam): 0.02
Elastic Net Parameter (elasticNetParam): 0.0
best_model.write().overwrite().save("best_model_LR_oversampled_reg")
import pandas as pd

# Extract the hyperparameters and their associated metrics
results = cvModel.avgMetrics

# Create a DataFrame with hyperparameters and metrics
param_keys = ['regParam', 'elasticNetParam']
data = {'regParam': [], 'elasticNetParam': [], 'Accuracy': []}

for i in paramGrid:
    list_vals = list(i.values())
    data['regParam'].append(list_vals[0])
    data['elasticNetParam'].append(list_vals[1])
data['Accuracy'] = cvModel.avgMetrics


df = pd.DataFrame(data)
df.to_csv("hyperparameter_tuning_LR_oversampled.csv", index = False)

Inferences using best model:

test.printSchema()
root
 |-- body_length: integer (nullable = true)
 |-- subreddit: string (nullable = true)
 |-- controversiality: long (nullable = true)
 |-- env_bool: integer (nullable = false)
 |-- claim_bool: integer (nullable = false)
 |-- sentiment_result: string (nullable = true)
 |-- skeptic_site: boolean (nullable = true)
 |-- gilded: long (nullable = true)
 |-- score: long (nullable = true)
 |-- subreddit_indexed: double (nullable = false)
 |-- subreddit_encoded: vector (nullable = true)
 |-- sentiment_result_indexed: double (nullable = false)
 |-- sentiment_result_encoded: vector (nullable = true)
 |-- features: vector (nullable = true)
 |-- Scaled_features: vector (nullable = true)
from pyspark.ml.classification import LogisticRegressionModel
loaded_lr_model = LogisticRegressionModel.load("best_model_LR_oversampled_reg")
predictions_train = loaded_lr_model.transform(test)
predictions_train.printSchema()
# predictions_train.show()
root
 |-- body_length: integer (nullable = true)
 |-- subreddit: string (nullable = true)
 |-- controversiality: long (nullable = true)
 |-- env_bool: integer (nullable = false)
 |-- claim_bool: integer (nullable = false)
 |-- sentiment_result: string (nullable = true)
 |-- skeptic_site: boolean (nullable = true)
 |-- gilded: long (nullable = true)
 |-- score: long (nullable = true)
 |-- subreddit_indexed: double (nullable = false)
 |-- subreddit_encoded: vector (nullable = true)
 |-- sentiment_result_indexed: double (nullable = false)
 |-- sentiment_result_encoded: vector (nullable = true)
 |-- features: vector (nullable = true)
 |-- Scaled_features: vector (nullable = true)
 |-- rawPrediction: vector (nullable = true)
 |-- probability: vector (nullable = true)
 |-- prediction: double (nullable = false)


# assembler = VectorAssembler(inputCols=["body_length", 
#                                        "controversiality",  
#                                        "subreddit_encoded",
#                                        "sentiment_result_encoded",
#                                        "skeptic_site",
#                                       "env_bool", 
#                                        "gilded", 
#                                        "score"], outputCol="features")
train.select("skeptic_site").distinct().show()
[Stage 6395:=====================================>                  (2 + 1) / 3]                                                                                
+------------+
|skeptic_site|
+------------+
|        true|
|       false|
+------------+
profile_df = predictions_train.groupBy("prediction", "sentiment_result", "subreddit", "controversiality") \
              .agg(F.count("*").alias("count"),
                   F.mean("body_length").alias("mean_length"),
                   F.mean("score").alias("mean_score"),
                 F.sum(F.when(predictions_train["gilded"] == 1, 1).otherwise(0)).alias("sum_gilded"),
                  F.sum(F.when(predictions_train["skeptic_site"] == True, 1).otherwise(0)).alias("sum_skeptic_site"),
                  F.sum(F.when(predictions_train["env_bool"] == 1, 1).otherwise(0)).alias("sum_env"))

profile_df = profile_df.orderBy("prediction")
# "env", "gilded", "edited_bool", "skeptic_site" 
import pandas as pd
profile_df = profile_df.toPandas()
profile_df.to_csv('inference_model_profiles.csv', index=False)
                                                                                
# loaded_lr_model.coefficients
# oversampled_train_df.printSchema()
# from pyspark.ml.feature import VectorAssembler

# # Assuming 'loaded_lr_model' is your loaded Logistic Regression model

# # Get the feature names from the feature vector assembler used in training
# # feature_names = loaded_lr_model.stages[0].getInputCols()

# # Get the coefficients
# coefficients = loaded_lr_model.coefficients

# # Create a DataFrame with feature names and importances
# feature_importance_df = pd.DataFrame({"Feature": feature_names, "Importance": coefficients})

# # Save the DataFrame to a CSV file
# feature_importance_df.to_csv("feature_importance.csv", index=False)

ML Illustrations: Run only this if you want to change illustrations:


import json
import matplotlib.pyplot as plt
import seaborn as sns

json_path = "ml_metrics_comparison_oversampled.json"

with open(json_path, 'r') as json_file:
    confusion_data = json.load(json_file)


cm_lr = confusion_data['lr_cm_oversampled']
cm_xg = confusion_data['xg_cm_oversampled']

#################################### Beginning plotting: 

fig, axes = plt.subplots(1, 2, figsize=(16, 6))

# LR:
sns.heatmap(cm_lr, annot=True, fmt="d", cmap="Blues", xticklabels=['Claim', 'No Claim'], yticklabels=['Claim', 'No Claim'], ax=axes[0])
axes[0].set_xlabel('Predicted Labels'); axes[0].set_ylabel('True Labels')
axes[0].set_title('Logistic Regression')
axes[0].annotate(f"Accuracy: {confusion_data['lr_acc_oversampled_oversampled']:.3f}", xy=(0.5, -0.15), xycoords='axes fraction', ha='center', va='center')

# GBThing
sns.heatmap(cm_xg, annot=True, fmt="d", cmap="Blues", xticklabels=['Claim', 'No Claim'], yticklabels=['Claim', 'No Claim'], ax=axes[1])
axes[1].set_xlabel('Predicted Labels')
axes[1].set_ylabel('True Labels')

axes[1].set_title('GBT Classifier')

axes[1].annotate(f"Accuracy: {confusion_data['xg_acc_oversampled']:.3f}", xy=(0.5, -0.15), xycoords='axes fraction', ha='center', va='center')

# plt.tight_layout()
plt.subplots_adjust(bottom=0.15)

plt.suptitle("Figure 5: Evaluation of Different Algorithms")

plt.savefig('model_comparison_accuracy_oversampled.jpg')

plt.show()
    

df = pd.read_csv('hyperparameter_tuning_LR_oversampled.csv')
heatmap_data = df.pivot_table(index="regParam", columns="elasticNetParam", values="Accuracy")

import seaborn as sns
import matplotlib.pyplot as plt

plt.figure(figsize=(8, 6))
sns.heatmap(heatmap_data, annot=True, cmap="YlGnBu", fmt=".4f", cbar=True)
plt.title("Figure 6: Hyperparameter Tuning Results for Logistic Regression")
plt.xlabel("Elastic Net")
plt.ylabel("Regularization")
plt.savefig('hyperparameter_lr_oversampled.jpg')
plt.show()